
Last updated: October 17, 2026
A SQL Server health check is a read-only review of an instance’s recoverability, integrity, configuration, performance, and security. It answers a few direct questions: are backups and DBCC CHECKDB current, are the settings sensible, what is the server waiting on, and who can get in? This page gives you the checklist, free T-SQL scripts to run it yourself, and an example of a finished report.
Health checks usually start because of one of four problems:
- Slow query performance. Queries are degrading, but nobody can say whether the cause is missing indexes, bad plans, or resource contention.
- Deadlocks and blocking. Applications time out and the root cause is buried in system views.
- Security unknowns. Are connections encrypted? Who has sysadmin?
- Configuration drift. Settings have changed over the years and nobody knows whether they are still sensible, or even safe.
SQL Server health check checklist
The table lists what to check in each area and where SQL Server keeps the answer. The last column points to the matching script in the next section.
| Area | What to check | Where the data lives | Script |
|---|---|---|---|
| Backups | Last full, differential, and log backup per database; log backup gaps in the FULL recovery model | msdb.dbo.backupset | 3 |
| Integrity | Last successful DBCC CHECKDB per database | DATABASEPROPERTYEX(..., 'LastGoodCheckDbTime'), DBCC DBINFO | 4 |
| Waits | What the server spends its time waiting on | sys.dm_os_wait_stats | 1 |
| Storage | Read and write latency per database file | sys.dm_io_virtual_file_stats | 2 |
| Transaction log | VLF count, log size, and why the log can’t truncate | sys.dm_db_log_stats | 9 |
| File growth | Percent growth, small increments, disabled growth, files near their size cap | sys.master_files | 8 |
| tempdb | Data file count against logical CPUs; equal sizes and growth | tempdb.sys.database_files | 10 |
| Database options | AUTO_SHRINK, AUTO_CLOSE, PAGE_VERIFY, automatic statistics | sys.databases | 7 |
| Instant file initialization | Enabled for the SQL Server service account | sys.dm_server_services | 11 |
| Encryption | Whether each user connection is encrypted | sys.dm_exec_connections | 5 |
| Privileged access | Who is a member of sysadmin | sys.server_role_members | 6 |
| Memory | Queries waiting for a memory grant | sys.dm_exec_requests, sys.dm_exec_query_memory_grants | 12 |
| Instance settings | MAXDOP, cost threshold for parallelism, max server memory | sys.configurations | — |
| Version and patching | Build and cumulative update level | SERVERPROPERTY | — |
| Workload | Top queries by CPU; share of single-use plans in the plan cache | sys.dm_exec_query_stats, sys.dm_exec_cached_plans | — |
| Indexes | High-value missing indexes | sys.dm_db_missing_index_* | — |
| Query Store | State, storage used, and capture mode per database | sys.database_query_store_options | 13 |
| Deadlocks | Deadlocks in the last seven days | system_health Extended Events session | — |
| Availability groups | Synchronization state, log send and redo queues | sys.dm_hadr_database_replica_states | — |
Run it yourself: free T-SQL health check scripts
These scripts are adapted from the queries AI SQL Tuner Studio’s Server Health Check runs. All of them are read-only: they select from system views and change nothing. Run them in SQL Server Management Studio or any query tool against SQL Server or Azure SQL Managed Instance.
Most of them need the VIEW SERVER STATE permission, and script 3 needs read access to msdb. To set up a login with only the access a health check needs, see Least Privileged Account Creation.
Wait, I/O, and plan cache figures are cumulative since SQL Server last started, so run the scripts after the server has handled a normal workload, not just after a restart.
1. Top waits since the last restart
WITH WaitStats AS (
    SELECT wait_type,
           waiting_tasks_count,
           wait_time_ms,
           max_wait_time_ms,
           signal_wait_time_ms,
           wait_time_ms - signal_wait_time_ms AS resource_wait_time_ms,
           CAST(1.0 * wait_time_ms / NULLIF(waiting_tasks_count, 0) AS DECIMAL(12, 2)) AS avg_wait_ms,
           CAST(100.0 * wait_time_ms / SUM(wait_time_ms) OVER () AS DECIMAL(5, 2)) AS percentage_of_total_waits,
           CAST(wait_time_ms / 1000.0 / 60.0 AS DECIMAL(12, 2)) AS wait_time_minutes
    FROM sys.dm_os_wait_stats
    WHERE wait_type NOT IN (
        'CLR_SEMAPHORE', 'LAZYWRITER_SLEEP', 'RESOURCE_QUEUE', 'SLEEP_TASK',
        'SLEEP_SYSTEMTASK', 'SQLTRACE_BUFFER_FLUSH', 'WAITFOR', 'LOGMGR_QUEUE',
        'CHECKPOINT_QUEUE', 'REQUEST_FOR_DEADLOCK_SEARCH', 'XE_TIMER_EVENT',
        'BROKER_TO_FLUSH', 'BROKER_TASK_STOP', 'CLR_MANUAL_EVENT',
        'CLR_AUTO_EVENT', 'DISPATCHER_QUEUE_SEMAPHORE', 'FT_IFTS_SCHEDULER_IDLE_WAIT',
        'XE_DISPATCHER_WAIT', 'XE_DISPATCHER_JOIN', 'SQLTRACE_INCREMENTAL_FLUSH_SLEEP',
        'ONDEMAND_TASK_QUEUE', 'BROKER_EVENTHANDLER', 'SLEEP_BPOOL_FLUSH',
        'DIRTY_PAGE_POLL', 'HADR_FILESTREAM_IOMGR_IOCOMPLETION',
        'SP_SERVER_DIAGNOSTICS_SLEEP', 'SOS_WORK_DISPATCHER')
      AND wait_time_ms > 0
)
SELECT TOP (10)
       wait_type,
       waiting_tasks_count,
       avg_wait_ms,
       max_wait_time_ms,
       signal_wait_time_ms,
       resource_wait_time_ms,
       percentage_of_total_waits,
       wait_time_minutes
FROM WaitStats
WHERE percentage_of_total_waits > 1.0
ORDER BY wait_time_ms DESC;
What bad looks like: a few wait types account for most of the time. PAGEIOLATCH_* and WRITELOG point to storage, LCK_M_* to blocking, RESOURCE_SEMAPHORE to queries waiting for memory, and SOS_SCHEDULER_YIELD to CPU pressure. Microsoft’s guidance is that I/O waits such as PAGEIOLATCH_* and WRITELOG should generally stay below 10–15 ms per request; avg_wait_ms shows the average for each wait type. On Azure SQL Database, use sys.dm_db_wait_stats instead.
2. I/O latency by database file
SELECT TOP (20)
       DB_NAME(vfs.database_id) AS database_name,
       mf.name AS file_logical_name,
       mf.type_desc AS file_type,
       mf.physical_name,
       vfs.num_of_reads,
       CASE WHEN vfs.num_of_reads = 0 THEN 0
            ELSE vfs.io_stall_read_ms / vfs.num_of_reads END AS avg_read_latency_ms,
       vfs.num_of_writes,
       CASE WHEN vfs.num_of_writes = 0 THEN 0
            ELSE vfs.io_stall_write_ms / vfs.num_of_writes END AS avg_write_latency_ms,
       vfs.io_stall_read_ms + vfs.io_stall_write_ms AS total_io_stall_ms
FROM sys.dm_io_virtual_file_stats(NULL, NULL) AS vfs
INNER JOIN sys.master_files AS mf
        ON vfs.database_id = mf.database_id
       AND vfs.file_id = mf.file_id
WHERE vfs.num_of_reads > 0 OR vfs.num_of_writes > 0
ORDER BY vfs.io_stall_read_ms + vfs.io_stall_write_ms DESC;
What bad looks like: average read or write latency that is consistently above 10–15 ms, the range Microsoft uses as an approximate threshold for I/O problems. Because the numbers are averages since startup, a file can look fine here and still have bad periods; check the wait statistics and Performance Monitor’s Avg. Disk sec/Transfer counter if users report slowness at particular times.
3. Backup and recovery status
WITH last_backups AS (
    SELECT d.name AS database_name,
           d.database_id,
           d.recovery_model_desc,
           MAX(CASE WHEN b.type = 'D' THEN b.backup_finish_date END) AS last_full_backup,
           MAX(CASE WHEN b.type = 'I' THEN b.backup_finish_date END) AS last_diff_backup,
           MAX(CASE WHEN b.type = 'L' THEN b.backup_finish_date END) AS last_log_backup
    FROM sys.databases AS d
    LEFT JOIN msdb.dbo.backupset AS b
           ON b.database_name = d.name
    GROUP BY d.name, d.database_id, d.recovery_model_desc
)
SELECT database_name,
       recovery_model_desc,
       last_full_backup,
       last_diff_backup,
       last_log_backup,
       DATEDIFF(DAY, last_full_backup, GETDATE()) AS days_since_full,
       DATEDIFF(HOUR, last_log_backup, GETDATE()) AS hours_since_log,
       CASE WHEN last_full_backup IS NULL THEN 1 ELSE 0 END AS no_full_backup,
       CASE WHEN recovery_model_desc = 'FULL' AND last_log_backup IS NULL
            THEN 1 ELSE 0 END AS full_recovery_no_log_backups,
       CASE WHEN recovery_model_desc = 'FULL' AND last_log_backup IS NOT NULL
                 AND DATEDIFF(HOUR, last_log_backup, GETDATE()) > 4
            THEN 1 ELSE 0 END AS long_gap_in_log_backups,
       CASE WHEN recovery_model_desc = 'FULL' AND last_full_backup IS NOT NULL
                 AND last_log_backup IS NOT NULL AND last_log_backup < last_full_backup
            THEN 1 ELSE 0 END AS log_backup_older_than_full
FROM last_backups
WHERE database_name <> N'tempdb'
ORDER BY database_id;
What bad looks like: no_full_backup = 1 on any database you need to keep; a database in the FULL recovery model with no log backups, whose log will keep growing; more than four hours since the last log backup (AI SQL Tuner Studio’s default flag; compare it with your recovery point objective); or no log backup since the most recent full backup. The query only sees backups recorded in msdb, so backups taken outside SQL Server, such as some storage snapshots, won’t appear.
4. Last known good DBCC CHECKDB
SELECT name AS database_name,
       CASE WHEN CAST(DATABASEPROPERTYEX(name, 'LastGoodCheckDbTime') AS DATETIME) = '19000101'
            THEN NULL
            ELSE CAST(DATABASEPROPERTYEX(name, 'LastGoodCheckDbTime') AS DATETIME) END AS last_good_checkdb,
       DATEDIFF(DAY, CAST(DATABASEPROPERTYEX(name, 'LastGoodCheckDbTime') AS DATETIME), GETDATE()) AS days_since_checkdb
FROM sys.databases
WHERE name <> N'tempdb'
  AND state_desc = N'ONLINE'
ORDER BY days_since_checkdb DESC;
What bad looks like: a NULL last_good_checkdb, meaning SQL Server has no record of a successful CHECKDB, or a date older than your integrity-check schedule. AI SQL Tuner Studio flags databases at more than 7 days and treats more than 30 days as critical. LastGoodCheckDbTime is available on SQL Server 2016 SP2 and later; the app reads DBCC DBINFO first and falls back to this property.
5. Connection encryption
SELECT TOP (50)
       c.session_id,
       c.net_transport,
       c.encrypt_option,
       c.auth_scheme,
       c.client_net_address,
       c.local_tcp_port,
       s.login_name,
       s.host_name,
       s.program_name
FROM sys.dm_exec_connections AS c
JOIN sys.dm_exec_sessions AS s
  ON c.session_id = s.session_id
WHERE s.is_user_process = 1
ORDER BY c.encrypt_option, c.net_transport, c.local_tcp_port;
What bad looks like: encrypt_option = FALSE on TCP connections, which means data travels unencrypted between the client and the server. The fix is Encrypt=True in connection strings, a trusted TLS certificate on the server, and Force Encryption in SQL Server Configuration Manager.
6. Members of the sysadmin role
SELECT sp.name AS login_name,
       sp.type_desc
FROM sys.server_role_members AS srm
JOIN sys.server_principals AS sp
  ON srm.member_principal_id = sp.principal_id
JOIN sys.server_principals AS rp
  ON srm.role_principal_id = rp.principal_id
WHERE rp.name = N'sysadmin'
  AND sp.is_disabled = 0
  AND sp.name NOT LIKE 'NT SERVICE\%'
ORDER BY sp.name;
What bad looks like: anyone on the list who doesn’t need full control of the instance. AI SQL Tuner Studio notes more than 5 members, warns at more than 10, and calls out sa, BUILTIN groups, and NT AUTHORITY accounts. The query skips disabled logins and NT SERVICE accounts. It doesn’t apply to Azure SQL Database.
7. Database options audit
SELECT name,
       compatibility_level,
       recovery_model_desc,
       page_verify_option_desc,
       is_auto_close_on,
       is_auto_shrink_on,
       is_auto_create_stats_on,
       is_auto_update_stats_on,
       is_auto_update_stats_async_on,
       is_read_committed_snapshot_on,
       snapshot_isolation_state_desc
FROM sys.databases
WHERE database_id > 4
  AND state_desc = 'ONLINE'
ORDER BY name;
What bad looks like: is_auto_close_on = 1 or is_auto_shrink_on = 1, a page_verify_option_desc other than CHECKSUM, automatic statistics creation or update turned off, or a compatibility level below what your SQL Server version supports.
8. Risky file autogrowth settings
SELECT DB_NAME(mf.database_id) AS database_name,
       mf.name AS logical_name,
       mf.type_desc,
       CAST(mf.size * 8.0 / 1024 AS DECIMAL(14, 1)) AS size_mb,
       CASE WHEN mf.is_percent_growth = 1 THEN CAST(mf.growth AS VARCHAR(20)) + '%'
            WHEN mf.growth = 0 THEN 'DISABLED'
            ELSE CAST(CAST(mf.growth * 8.0 / 1024 AS DECIMAL(14, 1)) AS VARCHAR(24)) + ' MB' END AS growth_setting,
       CASE WHEN mf.max_size IN (-1, 268435456) THEN NULL
            ELSE CAST(mf.max_size * 8.0 / 1024 AS DECIMAL(14, 1)) END AS max_size_mb,
       CASE WHEN mf.is_percent_growth = 1 THEN 'Percent growth'
            WHEN mf.growth = 0 THEN 'Autogrowth disabled'
            WHEN mf.growth * 8.0 / 1024 < 64 THEN 'Growth increment under 64 MB'
            ELSE 'Within 10% of max size' END AS risk_reason
FROM sys.master_files AS mf
INNER JOIN sys.databases AS d
        ON d.database_id = mf.database_id
WHERE d.state_desc = 'ONLINE'
  AND d.database_id > 4
  AND (mf.is_percent_growth = 1
       OR mf.growth = 0
       OR (mf.is_percent_growth = 0 AND mf.growth > 0 AND mf.growth * 8.0 / 1024 < 64)
       OR (mf.max_size NOT IN (-1, 268435456) AND mf.size >= mf.max_size * 0.9))
ORDER BY database_name, mf.file_id;
What bad looks like: any row. The query returns only files with percentage growth, a fixed increment under 64 MB, growth disabled, or less than 10% headroom below a maximum size. The risk_reason column says which.
9. Transaction log health
SELECT d.name AS database_name,
       ls.total_vlf_count,
       ls.active_vlf_count,
       CAST(ls.total_log_size_mb AS DECIMAL(14, 1)) AS total_log_size_mb,
       CAST(ls.active_log_size_mb AS DECIMAL(14, 1)) AS active_log_size_mb,
       ls.log_truncation_holdup_reason
FROM sys.databases AS d
CROSS APPLY sys.dm_db_log_stats(d.database_id) AS ls
WHERE d.state_desc = 'ONLINE'
  AND d.database_id > 4
ORDER BY ls.total_vlf_count DESC;
What bad looks like: a high total_vlf_count (Microsoft’s documentation uses more than 100 as its example threshold, because many VLFs slow database startup, restore, and recovery) or a log_truncation_holdup_reason such as LOG_BACKUP or ACTIVE_TRANSACTION, which means the log can’t be reused and will keep growing. Requires SQL Server 2016 SP2 or later.
10. tempdb file layout
SELECT (SELECT cpu_count FROM sys.dm_os_sys_info) AS logical_cpu_count,
       f.name,
       f.type_desc,
       CAST(f.size * 8.0 / 1024 AS DECIMAL(14, 1)) AS size_mb,
       CASE WHEN f.is_percent_growth = 1 THEN CAST(f.growth AS VARCHAR(20)) + '%'
            WHEN f.growth = 0 THEN 'DISABLED'
            ELSE CAST(CAST(f.growth * 8.0 / 1024 AS DECIMAL(14, 1)) AS VARCHAR(24)) + ' MB' END AS growth_setting
FROM tempdb.sys.database_files AS f
ORDER BY f.type, f.file_id;
What bad looks like: fewer data files than Microsoft recommends, or data files of different sizes or growth settings. Microsoft’s guidance: with eight or fewer logical processors, use one data file per processor; with more than eight, start with eight files and add them in multiples of four only if allocation contention continues. Data files should all be the same size.
11. Instant file initialization
SELECT servicename,
       service_account,
       instant_file_initialization_enabled
FROM sys.dm_server_services
WHERE servicename LIKE 'SQL Server (%';
What bad looks like: instant_file_initialization_enabled = N. Without it, SQL Server writes zeros over new space when data files grow or databases are restored, which makes those operations slower. Doesn’t apply to Azure SQL or Amazon RDS, where the platform manages it.
12. Queries waiting for memory right now
SELECT r.session_id,
       r.wait_time AS wait_time_ms,
       mg.requested_memory_kb,
       mg.granted_memory_kb,
       SUBSTRING(t.text, r.statement_start_offset / 2 + 1,
                 (CASE WHEN r.statement_end_offset = -1
                       THEN LEN(CONVERT(NVARCHAR(MAX), t.text)) * 2
                       ELSE r.statement_end_offset END - r.statement_start_offset) / 2 + 1) AS sql_text
FROM sys.dm_exec_requests AS r
LEFT JOIN sys.dm_exec_query_memory_grants AS mg
       ON r.session_id = mg.session_id
OUTER APPLY sys.dm_exec_sql_text(r.sql_handle) AS t
WHERE r.wait_type = 'RESOURCE_SEMAPHORE';
What bad looks like: any row. Each one is a query queued for a memory grant before it can start. Run the script a few times during busy periods; an empty result at one moment doesn’t rule out memory-grant pressure at another.
13. Query Store state
-- Run in each user database
SELECT DB_NAME() AS database_name,
       desired_state_desc,
       actual_state_desc,
       readonly_reason,
       current_storage_size_mb,
       max_storage_size_mb,
       query_capture_mode_desc
FROM sys.database_query_store_options;
What bad looks like: actual_state_desc different from desired_state_desc, or READ_ONLY with a readonly_reason of 65536, which means Query Store reached its maximum storage size and stopped capturing new data. OFF on a database where you need query plan history for troubleshooting regressions is also worth fixing.
What a health check report looks like
A health check report should give you a short assessment, a prioritized list of findings with the evidence behind each one, and the scripts to fix them. AI SQL Tuner Studio’s report has an executive summary, status tiles for the most important findings, prioritized recommendations with confidence ratings, and a Scripts section you can save as a .sql file.
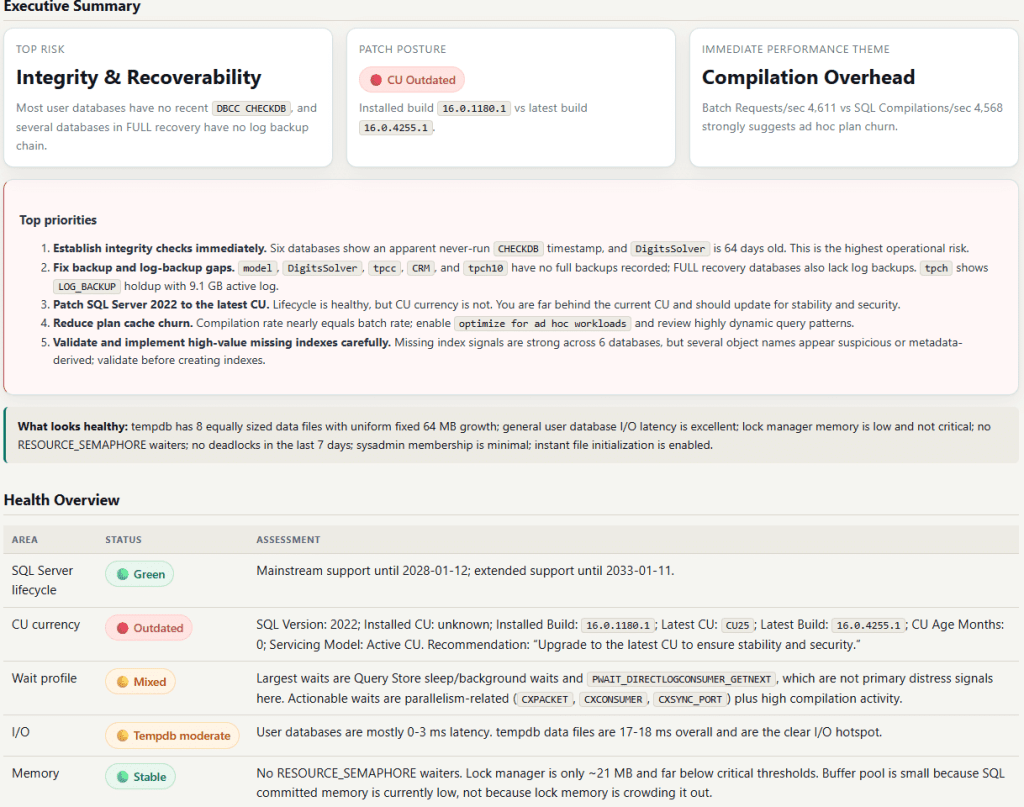
Here is a sample health check report generated against a SQL Server 2022 Developer Edition instance with multiple databases, using GPT-5.6 Luna at Medium reasoning effort. Its main findings:
- Lifecycle and patch status. SQL Server 2022 showed 🟢 Green lifecycle status (mainstream support runs through January 2028) but 🔴 Outdated CU currency: the instance was on build 16.0.1200.5, while the latest cumulative update, CU25, is build 16.0.4255.1.
- Critical: no DBCC CHECKDB history. Eighteen databases reported January 1, 1900 as their last integrity check, the value SQL Server returns when CHECKDB has never completed, and one more was 168 days overdue. The report included a CHECKDB script covering every affected database.
- Critical: missing backups and log holdups. Several databases had never had a full backup, and databases in the FULL recovery model had no log backups recorded. One database had 9.2 GB of its 10.5 GB log active and unable to truncate, waiting on a log backup.
- High: seven deadlocks in seven days. Three occurred within about 12 minutes. The report listed their timestamps and recommended the Fix Deadlocks goal.
- High: compilation pressure and database options. SQL compilations ran at 13,063 per second against 13,065 batch requests per second, with 37.5% of cached plans used only once. Five databases had automatic statistics creation and update turned off, and six log files used percentage-based autogrowth; the report included scripts for both.
- No memory pressure. No sessions were waiting on RESOURCE_SEMAPHORE, the lock manager cache was 1.38 MB, and tempdb had eight equally sized data files for 16 logical CPUs. The report also noted that the server had been running for only 37.4 hours, so its usage statistics covered a short window.
More example reports, including other Server Health Check runs, are on the AI SQL Tuner Studio Sample Reports site.
How to read the results
Work through the findings in priority order. Fix risks to data and recoverability first (missing CHECKDB, missing backups, a log that can’t truncate), then security exposure, then performance. Each AI SQL Tuner Studio recommendation carries a confidence rating: high means the evidence in the collected data is clear; medium or low means more investigation is needed first, and the report says what data is missing. Review and test every script in a non-production environment before you run it in production.
Automate the health check with AI SQL Tuner Studio
The scripts above cover the most common problems. AI SQL Tuner Studio’s Server Health Check runs these checks and more, sends the results to an AI model, and returns one prioritized report with scripts, typically in one to three minutes.
The video shows what a health check looks at, what it takes to run one by hand with DMV queries, and how the Server Health Check collects the same data and returns a report.
What the Server Health Check collects
Every query is read-only. Before each run, the Review run plan dialog lists every collector and the system views it reads.
- Performance: wait statistics, I/O latency per database file, the top 25 plan-cache queries by CPU (with memory grants and spills on SQL Server 2019 and later), plan-cache pollution from single-use plans, and batch requests and compilations per second.
- Configuration: CPU, memory, version, edition, and uptime; sp_configure settings; tempdb layout; risky file autogrowth; database options; and instant file initialization.
- Patching (on-premises SQL Server): lifecycle status against Microsoft’s support dates, and whether the installed cumulative update is current, one behind, or two or more behind the latest.
- Indexes and Query Store: high-value missing indexes, with the size of each table and its existing indexes, and Query Store settings for every database.
- Integrity and recovery: DBCC CHECKDB history, backup and recovery status, transaction log health, and availability group synchronization when availability groups are present.
- Security: connection encryption and sysadmin membership.
- Memory and concurrency: deadlocks from the last seven days, memory clerks, lock manager cache size, RESOURCE_SEMAPHORE waiters, top memory grants, buffer pool use by database, and lock counts by session.
Each report starts with the time SQL Server last started and its uptime, so you can see how much history the findings rest on.
Run it in four steps
- Connect. Open AI SQL Tuner Studio and select a connection in Connections, or click New to create one. A database is optional; Server Health defaults to
masterand checks every online user database. - Choose the goal. Under What should we tune today?, choose Server Health Check, then pick a MODEL and a REASONING level (Medium is the default).
- Run. Click Run Analysis, review the run plan, and click Send to AI.
- Review the report. The report streams into the HTML Output pane as it’s written. Save keeps the HTML report and Export SQL saves its scripts.
When the report finds a specific problem, the other goals go deeper: Index Tuning for indexes, SQL Query Tuner for an expensive query, and Fix Deadlocks for deadlocks.
Download AI SQL Tuner Studio Free: all six tuning goals, 10 analyses a month, every SQL Server platform, no credit card required. Paid editions add more analyses and AI models, with a 14-day free trial (credit card required) and a 30-day money-back guarantee on purchases from aisqltuner.com; see Compare Editions.
On Windows 10 or 11, you can also get AI SQL Tuner Studio from the Microsoft Store. It installs free, activates the Free edition with no license key, and updates automatically through the Store; paid editions are monthly subscriptions inside the app. Use the direct download instead on Windows Server, or if you want the 14-day free trial or the 30-day money-back guarantee, neither of which applies to Microsoft Store subscriptions. The FAQ explains the differences.
How often to run a SQL Server health check
Run the full check at least quarterly on production servers and monthly on mission-critical or fast-changing ones. Also run one after an upgrade, a migration, a major schema or workload change, or a hardware change. Keep the reports so you can compare runs and confirm that earlier fixes are holding.
Some checks are worth running more often than the full review:
- Daily: confirm that the previous night’s backups finished and that log backups are running on schedule (script 3), and check for failed SQL Server Agent jobs.
- Weekly: confirm that DBCC CHECKDB completed on every database (script 4) and look at log and file growth (scripts 8 and 9).
- Monthly or quarterly: run the full health check, including configuration, security, and performance.
Run it during a representative workload period, well after a restart. A check run on an idle or just-restarted server has little wait, query, or memory history to work with.
Azure SQL Database, Managed Instance, and Fabric
The Server Health Check runs on SQL Server 2016 and later, Azure SQL Managed Instance, Azure SQL Database, and Microsoft Fabric SQL Database. Where a platform doesn’t expose a view or manages a setting itself, the check skips it:
- Lifecycle and CU currency are checked only for on-premises SQL Server. Azure SQL Database, Azure SQL Managed Instance, and Fabric SQL Database are evergreen services with automatic version management.
- Deadlock history isn’t available on Azure SQL Database or Fabric SQL Database.
- tempdb and instant file initialization checks are skipped where the platform manages them. On Azure SQL Managed Instance, tempdb file count and size are platform-managed, so the report doesn’t recommend changing them.
- Instance-level checks such as sysadmin membership don’t apply to Azure SQL Database or Fabric SQL Database.
Permissions a health check needs
A health check needs VIEW SERVER STATE and VIEW DATABASE STATE. It doesn’t need sysadmin and makes no changes to the instance.
| Permission | Purpose | Scope |
|---|---|---|
| VIEW SERVER STATE | Most DMV queries, including deadlock history | Server |
| VIEW DATABASE STATE | Query Store settings | Each user database |
| sysadmin or db_owner | CHECKDB date through DBCC DBINFO; without it the check falls back to LastGoodCheckDbTime | Each user database |
| SELECT on msdb.dbo.backupset | Backup history | msdb |
If the report says it found no data, check that the login has these permissions and that the instance has been running under its normal workload.
Frequently asked questions
What is a SQL Server health check?
A SQL Server health check is a read-only review of a SQL Server instance that covers recoverability, integrity, configuration, performance, and security. It checks areas such as backups, DBCC CHECKDB history, wait statistics, I/O latency, configuration settings, connection encryption, and sysadmin membership to find risks and bottlenecks before they cause outages.
How often should I run a SQL Server health check?
Run one at least quarterly on production servers and monthly on mission-critical or fast-changing ones. Also run one after an upgrade, a migration, or a major schema or workload change.
What does a SQL Server health check report include?
A useful report has a short assessment, a prioritized list of findings with the evidence for each, and scripts to fix them. The AI SQL Tuner Studio report includes an executive summary, status tiles, prioritized recommendations with confidence ratings, and ready-to-run T-SQL scripts covering backups, integrity, configuration, patch currency, performance, memory, and security.
Can I run a SQL Server health check without a tool?
Yes. The free T-SQL scripts on this page check backups, CHECKDB history, waits, I/O latency, transaction log health, file growth, tempdb, database options, instant file initialization, connection encryption, sysadmin membership, memory grants, and Query Store state. They are read-only and need VIEW SERVER STATE. A tool saves you from running and interpreting each one by hand.
Does the health check change anything on my server?
No. Every query the health check runs is read-only, and the run plan shown before each run lists them all. Any fix the report recommends is delivered as a script for you to review, test, and run yourself.
Can I run a SQL Server health check for free?
Yes. The scripts on this page are free, and the AI SQL Tuner Studio Free edition runs the full Server Health Check on every SQL Server platform, with 10 analyses a month and no credit card required. Paid editions add more analyses and AI models, with a 14-day free trial and a 30-day money-back guarantee on purchases from aisqltuner.com.